

My AI agent doesn't forget code. It forgets why we made the decision
I've noticed a different kind of context problem while working with AI coding agents.
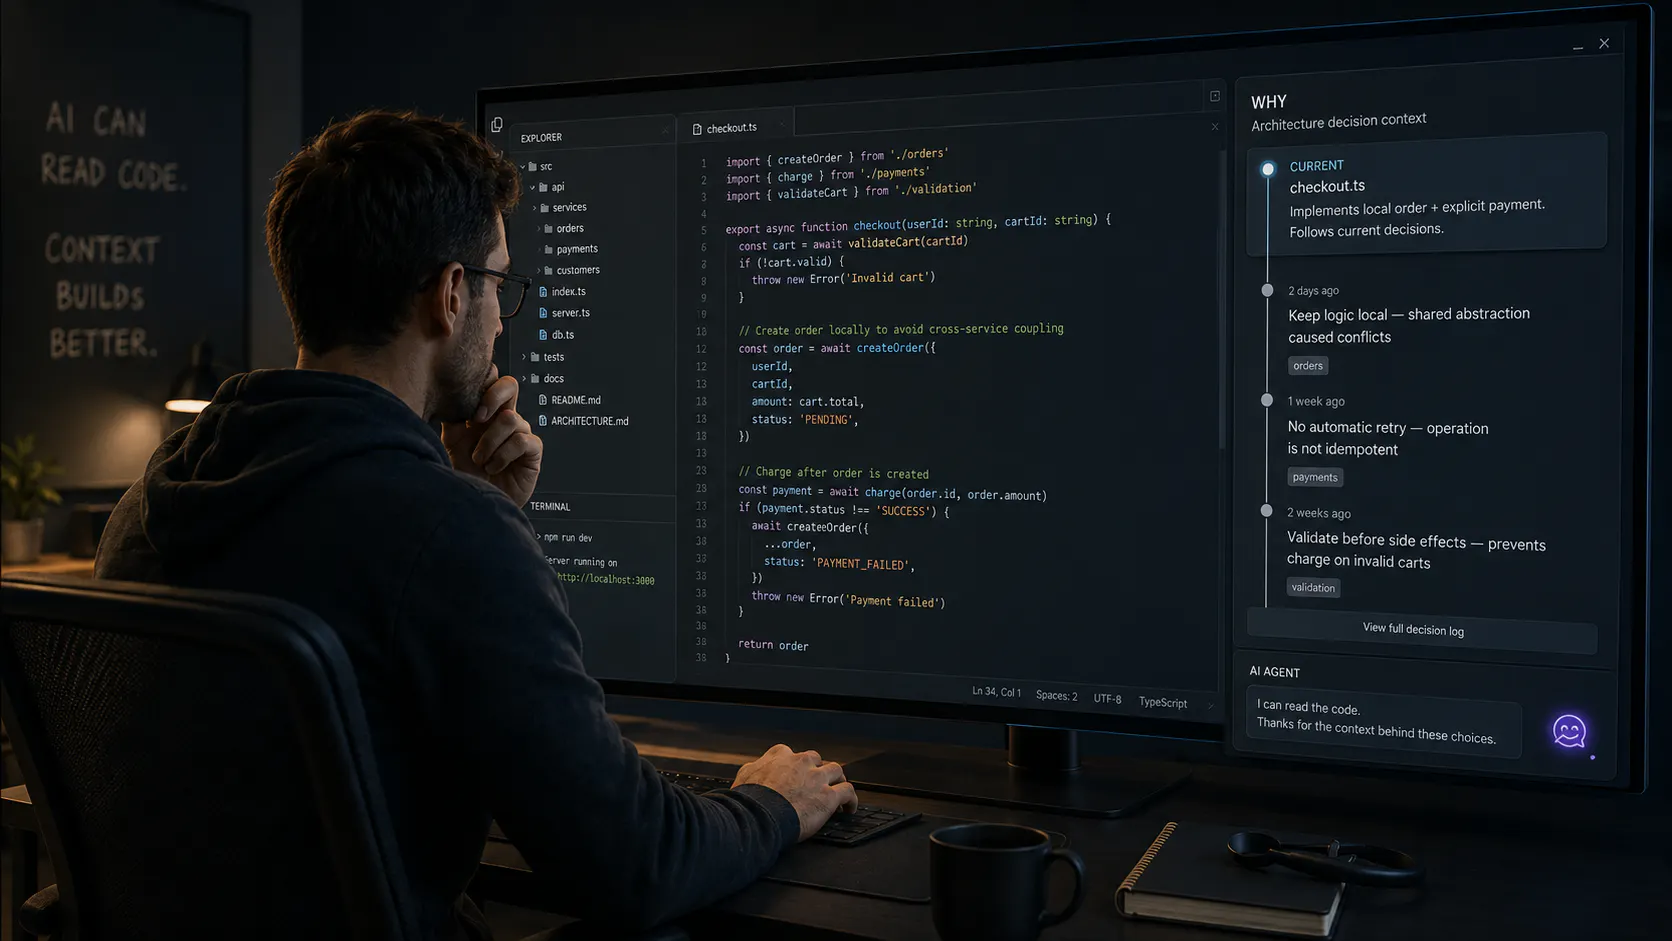
The agent can read the code.
It can inspect the git history.
It can find the files it needs.
But sometimes it still misses something important:
Why we made a particular decision in the first place.
For example:
Why we deliberately didn't use an abstraction
Why an API is handled differently in one workflow
Why a certain dependency is pinned
Why a seemingly duplicated piece of code exists
Why we chose a less elegant solution because of a product constraint
None of that is necessarily obvious from the code.
So I've started writing down decisions separately from implementation.
Not a huge document.
Just things like:
Decision: Keep this logic local.
Reason: The shared abstraction created problems with two existing workflows.
Or:
Decision: Don't auto-retry this request.
Reason: The operation isn't idempotent.
That small amount of context changes the next AI session quite a bit.
The agent isn't just seeing:
"Here's the code."
It's seeing:
"Here's the code, and here's why this code ended up this way."
I'm starting to think that as AI writes more of the codebase, decision history may become as important as documentation.
How are you preserving the reasoning behind architectural or product decisions in AI-assisted projects?
Replies
Agent wired early placeholder directyl into production reports. Output showed confident number nobody ever measured. Took us full day to trace back. Model made temporary stub into "permanent" code without keeping context it was fake
@konstantin_tikhaev That’s exactly the kind of failure mode I’m worried about.
The dangerous part isn't necessarily that the agent can't understand the code. It’s that it can misunderstand the status of the code — temporary stub, measured value, placeholder, experiment, or production logic.
Once that context disappears, the agent can make a perfectly reasonable change based on an incorrect assumption.
That makes “what is this code allowed to mean?” almost as important as “what does this code do?”
@evolvix_ai so we ended up adding explicit intent markers in the comments becasue the models treat any syntactically valid mock as the "production" truth )
@konstantin_tikhaev That’s a really practical solution. The interesting part is that the model isn’t necessarily failing to read the code — it’s missing the intent behind the code.
Explicit markers seem like a simple way to preserve that context without turning the codebase into a giant documentation project.
@evolvix_ai helps, we had to back markers with CI checks. left to itself agent just refactors comment away, uses mock anyway )
ADR files plus CLAUDE.md rules is what helped me.
The ADRs are the reasoning: one numbered file per decision, Context, Decision, Consequences, under a page. The CLAUDE.md rules are the short version the agent reads every session, and each rule carries the ADR number. So the rule says what to do, and the number says where the why lives. An agent opening the file sees "the approval scale (ADR 0041)" in the first comment and doesn't have to go looking.
The part I'd underline is Consequences: what I agreed to live with. That's the bit an agent otherwise silently "fixes".
Your two examples are already ADRs. They just need a number, and that number pasted into the code.
@fifthwye ADR + CLAUDE.md is a really clean way to separate the rule from the reason.
The Consequences part is especially important. Without it, an agent can see a constraint as something that should be “fixed” rather than something the team consciously chose to live with.
I also like the idea of putting the ADR number directly where the decision matters in the code. That makes the reasoning much easier to recover later.