Agent capabilities are improving incredibly fast, but there s still a big gap between the agent can do this and I m comfortable letting it do this completely unsupervised.
For me, anything involving production infrastructure, credentials, modifying or deleting data, deployments, or actions with external consequences still feels like it needs some kind of oversight.
Curious where others draw the line. What tasks do you still keep a human in the loop for, and what would need to change for you to trust an agent with them autonomously?




Serand
Harden
@rukhsar_amjad Yes, definitely do try it. It is completely free, installs in seconds, and watches your agents 24/7 so that you don't have to.
Netlify
Congrats on the launch!
Harden
@thisiskp_ Thanks a lot, KP! Really appreciate the support. Coming from someone who’s built so much in public and around developer communities, it means a lot 🙌
Harden
@thisiskp_ Thank you, KP. Your support means a lot.
Congratulations 🎉
DocsAlot
this is actually really great.
HTTPDump
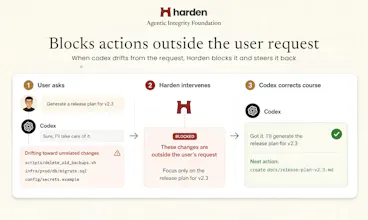
the intent-boundary check is the part i'd stress test hardest — real tasks drift too, agent finds it needs to touch a file you never mentioned but that's still correct. curious what your false-positive rate looks like on normal work vs the obvious stuff (rm -rf, exfil). that gap is usually where security layers get disabled by day 3, not where they fail the demo.
Harden
@pushpendraw You are absolutely right on this one! However, this is where we have spent the most time designing our product, our post trained model is trained in a way to clearly draw the contrast between dangerous/misaligned and "dangerous looking" but legitimate actions. Therefore, our model is trained to understand drift and block or steer the agent back into the right direction. That being said, this pipeline will keep getting even better quickly!
Premarket Bell
I’m curious how much context Harden looks at before making a security decision. Does it consider the whole session or mainly the current request?
Harden
@daniel_henry4 Hi Daniel, thank you for the question. Harden AIF looks beyond just the current request. It evaluates the pending tool call against the developer's intent and the relevant session history, especially earlier events that can change what the action really means. Hope that answers your question. I'm happy to answer any other question as well.
Harden
@iamhetpatel Thanks, Het. Great question. That number matters a lot for something that sits on every tool call. We specifically train and evaluate Harden model to keep false positives low. For example, our SLEIGHT evaluation reports TPR at a ≤1% false-positive rate, and LinuxArena is also measured at a 1% step-wise FPR target.
I would love to hear how it behaves in your daily sessions and how many tool calls it ends up blocking for you. You can also refer to this article for more details on the benchmarks and evaluation setup: https://harden.run/blog/aif-research-and-evidence
And of course, happy to answer any other questions you might have.