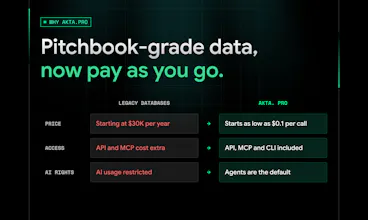
Private company data with 4x the depth and 2x the coverage of PitchBook, plus 100+ event signals and news across companies, industries, and topics. Source and diligence deals or make outreach lists and trigger outbound. Built for financial services and GTM teams, pay-as-you-go.
@veronica_ivy spot on, either data in isolation is commoditized. Tying signals to companies (particularly private) with entity resolution and de-duped is where the combination starts providing utility.
Report
I question how teams measure success after using this API. would the main benefit be saving research time or finding better business opportunities?
@new_user___209202627e87af67bf41b28 It shows up as time first and opportunities later. Week one is usually the boring win, where the cleaning and matching layer that used to sit in front of every agent just goes away, because the company data comes back structured and the news comes back already filtered instead of as pages to read through. That is also where the cost drops, since retrieval stops coming out of token spend. The better part comes later, when the signals start doing the work for you and a funding round or an exec change surfaces without anyone going to look for it. GTM teams count that in meetings booked, investment teams in deals they saw before the round was announced.
Reasoning models changed the economics of proprietary data. For years the winning move was a large team of analysts manually cleaning, normalizing and QAing structured datasets. That model is going obsolete.
Demand growth is in agents now, and agents do not want a handful of structured fields in a subscription model. They want a large, reliable corpus of structured qualitative knowledge they can reason over and scale consumption as needed. That changes how you architect the platform.
So we made entity resolution the foundation everything else sits on. Every company gets a canonical identity connecting parents, subsidiaries, products, executives, investors, news and hiring signals.
Once identity is solved, coverage stops being a fixed list you either have or lack and becomes an extensible graph, where anything new resolves against identities that already exist, including data you bring in yourself.
The real-time news pipeline runs on those same identities, with no batch refresh window. Every article goes through:
Deduplication and entity resolution back to company IDs
Classification against an 100+ event taxonomy
Mapping to NAICS, SIC, IAB and IPTC codes
Scoring for impact, sentiment and story centrality
Each of 20M+ companies are tagged to 30k+ industry codes and qualitative source-traceable data across 70+ fields.
The noise gets filtered along the way, and whatever survives is queryable the moment it lands.
The schema is built for reasoning over a corpus rather than browsing rows in a dashboard, which changes the interface too. Everything is API-first, with MCP and CLI as first-class surfaces built for token efficiency and composability inside agent workflows.
The goal is simple: make private markets data programmable for anyone building with AI.
Per seat pricing on company data always punished the wrong person, since I need enrichment in bursts around a campaign and then not at all for weeks. On the signals layer, how fast does something like a funding round or a hiring spike actually show up after it happens?
@yelyzaveta_kibets yes, per seat pricing has always constrained utility for several use-cases like you mentioned. On the signals layer - the events/news like funding rounds or hiring spikes show up the moment they are covered by any major publisher or platform. The News Signals APIs are real-time in that sense. So that your systems can identify trigger events the moment they occur without any time lag.
@siddhant_masson Real time on publisher coverage makes sense for funding, since somebody always writes that up. Hiring spikes are the ones nobody publishes though, so do you pick those up from job boards directly or wait for the coverage?
@yelyzaveta_kibets Good question, and directly from job boards rather than waiting for coverage. Hiring is one of our alternative signals, so we track postings and headcount ourselves rather than inferring them from articles.
That is the reason both exist side by side. News works for things somebody publishes, like funding or an exec change. Signals cover the things nobody writes up, which is where hiring spikes, headcount trends, web traffic and reviews live. A hiring spike usually shows up in postings well before it appears anywhere else, which is exactly when it is useful.
Both resolve to the same company IDs, so an event and a signal about the same business line up without any matching work.




The combination of private company data and real time signals is probably more useful than either one along.
akta.pro
@veronica_ivy spot on, either data in isolation is commoditized. Tying signals to companies (particularly private) with entity resolution and de-duped is where the combination starts providing utility.
I question how teams measure success after using this API. would the main benefit be saving research time or finding better business opportunities?
akta.pro
@new_user___209202627e87af67bf41b28 It shows up as time first and opportunities later. Week one is usually the boring win, where the cleaning and matching layer that used to sit in front of every agent just goes away, because the company data comes back structured and the news comes back already filtered instead of as pages to read through. That is also where the cost drops, since retrieval stops coming out of token spend. The better part comes later, when the signals start doing the work for you and a funding round or an exec change surfaces without anyone going to look for it. GTM teams count that in meetings booked, investment teams in deals they saw before the round was announced.
akta.pro
Happy to go deep on the technical side.
Reasoning models changed the economics of proprietary data. For years the winning move was a large team of analysts manually cleaning, normalizing and QAing structured datasets. That model is going obsolete.
Demand growth is in agents now, and agents do not want a handful of structured fields in a subscription model. They want a large, reliable corpus of structured qualitative knowledge they can reason over and scale consumption as needed. That changes how you architect the platform.
So we made entity resolution the foundation everything else sits on. Every company gets a canonical identity connecting parents, subsidiaries, products, executives, investors, news and hiring signals.
Once identity is solved, coverage stops being a fixed list you either have or lack and becomes an extensible graph, where anything new resolves against identities that already exist, including data you bring in yourself.
The real-time news pipeline runs on those same identities, with no batch refresh window. Every article goes through:
Deduplication and entity resolution back to company IDs
Classification against an 100+ event taxonomy
Mapping to NAICS, SIC, IAB and IPTC codes
Scoring for impact, sentiment and story centrality
Each of 20M+ companies are tagged to 30k+ industry codes and qualitative source-traceable data across 70+ fields.
The noise gets filtered along the way, and whatever survives is queryable the moment it lands.
The schema is built for reasoning over a corpus rather than browsing rows in a dashboard, which changes the interface too. Everything is API-first, with MCP and CLI as first-class surfaces built for token efficiency and composability inside agent workflows.
The goal is simple: make private markets data programmable for anyone building with AI.
Try for free. Code PH50 gets you 50 credits, no card required: playground.akta.pro/signup/?coupon_code=PH50 — If anything in the docs at https://docs.akta.pro/ is wrong or hard to follow, tell me and it usually gets fixed the same day
Dune
Interesting Concept. Congratulations on the Launch. @saswat_nanda2 @siddhant_masson @bharat_garg6
akta.pro
@dhanrajchoudhary Thanks a lot Dhanraj, appreciate the support
congrats on the launch!
akta.pro
@marupelkar Thanks Nakul!
Asset Money
akta.pro
@shivam_bhotika Thanks Shivam!
Softorino 💻📲
Per seat pricing on company data always punished the wrong person, since I need enrichment in bursts around a campaign and then not at all for weeks. On the signals layer, how fast does something like a funding round or a hiring spike actually show up after it happens?
akta.pro
@yelyzaveta_kibets yes, per seat pricing has always constrained utility for several use-cases like you mentioned. On the signals layer - the events/news like funding rounds or hiring spikes show up the moment they are covered by any major publisher or platform. The News Signals APIs are real-time in that sense. So that your systems can identify trigger events the moment they occur without any time lag.
Softorino 💻📲
@siddhant_masson Real time on publisher coverage makes sense for funding, since somebody always writes that up. Hiring spikes are the ones nobody publishes though, so do you pick those up from job boards directly or wait for the coverage?
akta.pro
@yelyzaveta_kibets Good question, and directly from job boards rather than waiting for coverage. Hiring is one of our alternative signals, so we track postings and headcount ourselves rather than inferring them from articles.
That is the reason both exist side by side. News works for things somebody publishes, like funding or an exec change. Signals cover the things nobody writes up, which is where hiring spikes, headcount trends, web traffic and reviews live. A hiring spike usually shows up in postings well before it appears anywhere else, which is exactly when it is useful.
Both resolve to the same company IDs, so an event and a signal about the same business line up without any matching work.
Softorino 💻📲
@siddhant_masson Postings moving first is the useful bit. How do you separate a real spike from a company that just reposts the same role every month?