
Pilot5.ai
Your question, deliberated by 5 frontier AI models
103 followers
Your question, deliberated by 5 frontier AI models
103 followers
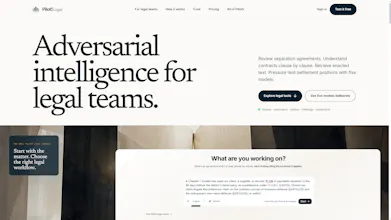
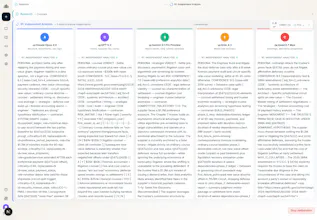
Pilot5.ai gives legal work an adversarial second opinion. Five frontier AI models analyze the same matter independently, challenge each other anonymously, and converge on a recommendation — while preserving the strongest objection. Research runs against primary legal sources, claims are tagged as sourced or inferred, and case citations are checked for existence. Built for lawyers who want AI analysis they can inspect, challenge, and defend.
This is the 2nd launch from Pilot5.ai. View more

Pilot5 Legal
Launching today
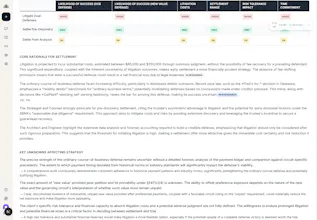
Pilot5 is relaunching for legal work. Five frontier AI models analyse the same matter independently, challenge each other’s reasoning, and converge on a recommendation while preserving the strongest opposing view. Pilot5 Legal adds primary-source research, citation verification, contract analysis, and transparent reasoning designed to help lawyers inspect, challenge, and verify AI output.


Launch Team

@thomaswainstein Five AI models challenging each other sounds impressive.. but how often do they actually disagree ?
hi @dipanshu_kushwaha5 everytime - we have manufactures a strucutre where we push for those disagreements to create a more diverse response and rich repsonse
congrats for launch @thomaswainstein 🙌 the idea of having specialized agents review the prompt process itself for bias is pretty next-level.
the part I'd push on is "independent" - five frontier models are mostly trained on overlapping web/legal corpora and share a lot of the same blind spots, so disagreement between them isn't the same as disagreement between five lawyers from different schools of thought. if all five miss the same obscure circuit split because none of them saw it in training, the convergence looks reassuring but means nothing. do you weight or flag the cases where all five agree but the agreement might just be a shared gap, or is consensus always treated as a positive signal
@galdayan your premise is right: five frontier models are not statistically independent. By “independent,” we mean different providers, weights and inference paths, not uncorrelated errors.
In the case you describe, the panel does not reason from training memory alone. Every deliberation combines model reasoning with live research across the web and allowlisted institutional sources, including CourtListener, Caselaw Access Project and the Federal Register. All five models then work from the same retrieved dossier. An obscure circuit split is therefore a retrieval problem before it is a model problem: if it is in the dossier, all five models can evaluate it.
The seats themselves are also designed to reduce groupthink. Each model has a different mandate, and one of them, the Contrarian, has a permanent brief to identify what the panel may be overlooking. If the panel converges too quickly, the orchestrator treats that as a warning signal rather than a result and triggers a Devil’s Advocate round against the emerging consensus.
Beyond the five-model panel, roughly 20 specialised agents continuously review the process itself: source quality, temperature and response variation, clarity, agreement patterns, revisions, and signs of manufactured consensus. Their role is to challenge not only the answer, but also how that answer was reached.
If the evidence base is too thin, Pilot5 lowers confidence or returns INSUFFICIENT BASIS rather than producing a reassuring verdict.
The residual gap you describe is real, and we do not claim to eliminate it. What changes is auditability: the record shows what was searched, what evidence was found, and what each claim rests on, so a shared gap becomes inspectable rather than remaining hidden inside one confident answer.
Weighting agreement by evidence coverage is a genuinely interesting direction. Put your hardest legal question through it; I’d honestly like to hear where it bends.