

Our AI Feature Passed the Spec—Then Real Data Exposed the Problem
We shipped an email attention-classification feature this week that passed every written requirement and was almost useless in production.
The system sorts business email into five tiers: Act now, Review today, Monitor, Routine, No action. Spec-compliant, tests green, ready to ship.
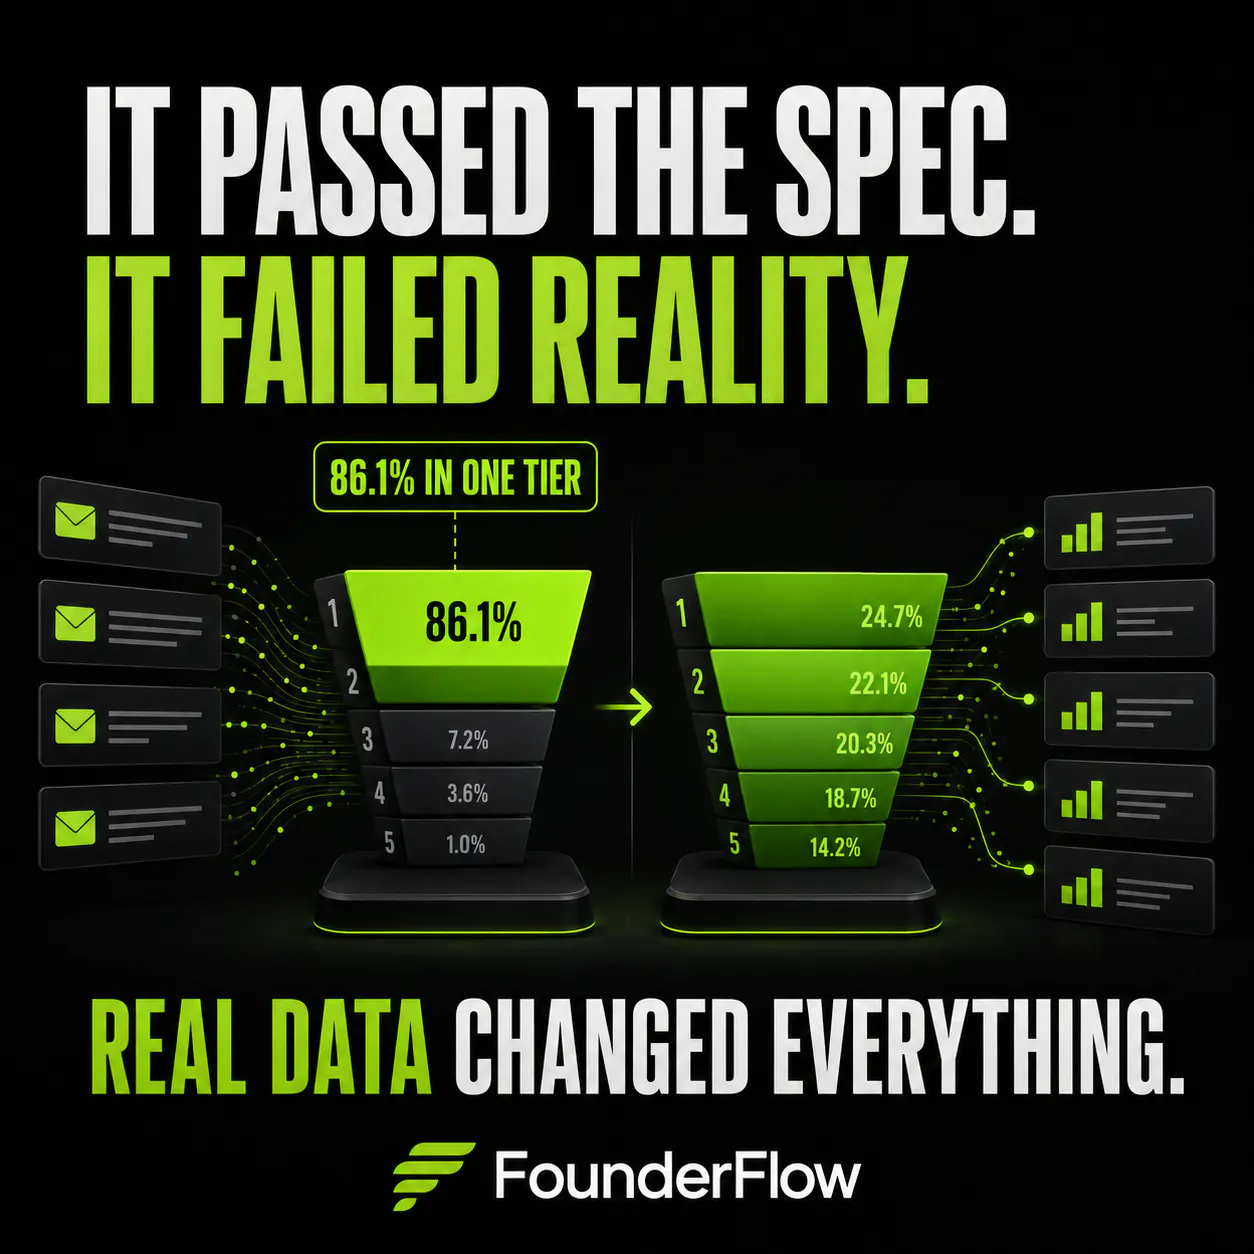
Then we ran it against real inbox data. 86.1% of everything landed in a single tier.
The labels weren't the problem. One of the signals feeding the classifier was also the default value assigned to unclassified emails. Every email missing that signal quietly inherited the default and got sorted the same way. In the spec it read as a sensible fallback. Against 6,000 real emails it collapsed the whole distribution.
After recalibrating:
Act now 3.2% / Review today 8.9% / Monitor 50.7% / Routine 33.4% / No action 3.8%
The same test run surfaced a second problem we weren't looking for: 222 emails still flagged as needing attention after the work was already done or archived. 27 were marked "Act now." The classifier had no concept of an item resolving itself.
Two things I took from it:
A default value that doubles as a real signal is indistinguishable from that signal downstream. Obvious in hindsight, invisible in the spec.
And "matches the specification" and "works" are separate claims. Our tests confirmed the code did what we wrote down. They couldn't tell us that what we wrote down was wrong.
Curious whether others have hit this: what's a feature that behaved exactly as specified and still failed the moment it met real data?
Replies