
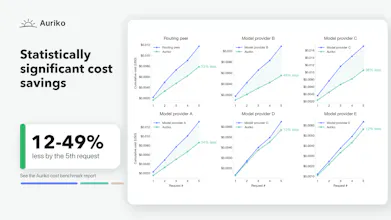
Auriko treats LLM providers as trading venues and arbitrages the spread. Built by ex-quant traders, Auriko’s cost-arbitrage engine calibrates to each user’s request patterns and selects optimized inference paths based on token price, cache behavior, latency, reliability, and request quality. Auriko benchmarks show average 30% cost reduction against industry peers and direct providers. See the source: https://www.auriko.ai/reports/llm-cost-arbitrage




Free Options
Launch Team

Floot MCPBuild and ship web and mobile apps inside Claude or ChatGPT
Promoted
Congrats on the PH launch! Modeling request patterns sounds helpful.
@anthony_cai Thank you for the support! give it a try!
This looks super useful for teams watching their AI bill climb every month. Congrats!
@yuki1028 Thanks!
Big congrats 🙌 Auriko feels practical and fresh, excited to test how it streamlines collaboration.
@moon10 Thanks!
@zxy_action1 Michael... this is jaw-dropping. I am beyond impressed by such a novel yet robust approach to token-spend reduction. My budget loves this!
(my brain, however...? it immediately wants to set about reverse-engineering this mf to tune it towards revenue generation... 😈)
Great work!!
@grey_seymour Glad you like it!
A 30% inference cost reduction that requires zero change to how our teams build is a rare operational win, and treating providers as trading venues is a genuinely clever framing.
@kelly_king3 Thanks!
Love the "trading desk for inference" framing—routing on cache behavior and real-time provider signals instead of just headline prices is exactly the kind of optimization most teams skip, and the zero-markup model makes it a no-brainer to try. Congrats on the launch! 🚀
@eeeeeach Thanks!
Nice launch! LLM cost optimization is exactly where a lot of teams need help right now.