
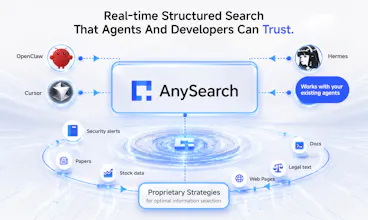
A search tool for agents, not a search box. AI agents are only as good as the information they receive. When connected to AnySearch, your agent gets filtered, de-duplicated, and structured information from trusted sources searched in parallel, helping it produce more reliable results. Free to start.


Launch Team

CloudflareStill paying to deploy your apps? Try Cloudflare Workers for free
Promoted


How does AnySearch decide which sources count as "trusted" for a given query, and can I override that list if I want to pull from a specific site or domain?
@sezerdasekwcwb Great question.
AnySearch does not use one fixed “trusted source” whitelist. Trust is query-dependent.
For each query, we rank sources based on signals like relevance, source authority, freshness, content type, domain fit, and vertical context. A trusted source for financial data may be very different from one for academic papers, legal research, or developer documentation.
Developers can also constrain or bias retrieval toward specific domains, sites, verticals, or source types when those sources are already covered or publicly accessible.
For new sites, private sources, or domains that are not yet covered, tell us the use case and target source. We can evaluate the best way to support it as a custom or approved source.
So the default is query-aware source selection, while developers can still enforce their own provenance policy when needed.
@sezerdasekwcwb Just chiming in here to add—we totally get that 'black box' APIs are a nightmare for agent builders.
That's why, alongside the input controls mentioned above, we focus heavily on output transparency. AnySearch always returns strict citation metadata, giving your system full auditability. You never have to blindly guess where the data came from!
Let us know if you have specific domains in mind for your use case.
@ridhwikvinod Thanks, and totally agree with that distinction — “trusted by the tool” is not always the same as “trusted by your workflow.”
Yes, the goal is to let developers control source policy per query.
For new domains, private sources, or sources that are not yet covered, share the use case and target sources with us. We can evaluate the best way to support them as custom or approved sources.
Default ranking is useful when developers do not want to manage source selection manually, but when you already have your own trusted source list, your policy should take priority.
@ridhwikvinod Thanks so much for the congrats!
Just adding a quick thought to Nic's answer: since messy results are your main headache, the best part of pinning those 15 domains is the output format.
We handle the extraction and just hand your agent clean Markdown. No more wrestling with raw HTML or scraping those specific sites.
Let us know if you want to test it out with your list!
@doaoww If you're curious, the fastest way to see how it compares for Google or Tavily is to use AnySearch for a few complex tasks in your Agent. I think you've seen search layer bottleneck of your Agent, especially multi-step queries. Would love to hear what the difference looks like in your Agent environment!
@doaoww @terence_lou I'm also curious to see some more objective and diverse benchmarking on different problems/tasks that require different kinds/depth of searching. Measuring the effect of AnySearch on the outcome. Time to reach the goal? Tokens? Result quality? The fact that search results were relevant and concise enough in a few test tasks is not convincing enough to me for serious prod adoption.
@doaoww @rezgar Thank you for your feedback again. If you want to get more objective and diverse benchmark test results about AnySearch, you can visit our official website www.anysearch.com to view. As time goes on, our product AnySearch is constantly evolving as the search layer of AI Agent, and more and more benchmark test results will be updated and displayed to the public.
@doaoww And thanks for your question~
the dedup and structuring part is the interesting bit to me, most "search for agents" pitches i've seen just wrap a regular search API. what happens when two trusted sources genuinely disagree on a fact, does anysearch pick one and present it as ground truth or does it surface both and let the agent reason about it
@omri_ben_shoham1
That's exactly the part that makes this interesting to me. Most "search for agents" pitches I've seen are just thin wrappers around a standard search API. The hard problem isn't "find relevant pages" — it's packing the most useful information into a limited context window.
So we didn't spend much effort on URL dedup — that's a relatively shallow problem. The real challenge is exactly what you described: different sources telling the same story with different wording, where reading three of them yields near-zero incremental information but burns through thousands of tokens.
The solution is a custom information-density ranking algorithm we built in-house. For multi-intent queries, the objective function isn't pure relevance — it's maximizing the information density of the final result set. Specifically, ranking jointly accounts for:
- Relevance — obviously can't go off-topic
- Cross-passage redundancy — how much a new passage overlaps with what's already in the selected set; high overlap gets down-weighted
- Information entropy — the passage's intrinsic information richness and distinctiveness
- Length penalty — given equal information value, shorter wins
This naturally answers your question — when two trusted sources genuinely disagree, it means each carries independent semantic information that the other lacks. They aren't redundant with each other. The algorithm won't pick one — both get included and surfaced. The agent sees a multifaceted, tension-rich information landscape and gets to reason, compare, and weigh things itself, rather than being fed a sanitized "canonical answer" with the contradictions already smoothed over.
At its core, what we're optimizing for is that every token the agent reads delivers maximum marginal information gain — not the same story rehashed three different ways. Disagreement between sources is actually one of the highest-information-density scenarios you can encounter. Suppressing it would actively degrade the value of the result set.
Makes sense, and I like that you're not trying to force a single "canonical" answer out of the model. My only worry with keeping disagreement in the set is cost - if two sources contradict each other you're now paying for both plus whatever reasoning tokens the agent burns reconciling them. Do you cap how many "genuinely conflicting" passages get surfaced per query, or is that left uncapped and trusted to the length penalty to sort itself out?
@omri_ben_shoham1 There's no specific cap — we keep as much diversity or disagreement as possible without exceeding the num_results the user requested.
got it, so it's whichever comes first - hitting the diversity target or hitting num_results. makes sense for a general default, just wondering if there's ever a case where a user wants strictly ranked results with zero diversity weighting (like a legal or medical search where you want the single best match, not variety)
the bit about agents not being able to skim and decide like humans is exactly the right framing — what does the output structure look like, json schema or more like markdown blocks?
@sabber_ahamed The structured content AnySearch provides is in Markdown format, which can be directly used by Agents. Existing search is designed for human browsing, that's why Agents cannot browse and make decisions like humans. AnySearch is designed to address this issue.
Heya! How is this better than https://parallel.ai/ for instance?
@conduit_design
Appreciate the question! Honestly, the best way to see the difference is to try it out yourself — we built AnySearch to be as easy to use as possible. Visit the official website and register an account to obtain more free search credits. We look forward to your feedback.
@conduit_design Fair question. Parallel looks like a strong product, so I’d frame it less as “better in every case” and more as a different focus.
Parallel seems very strong around open-web search, extraction, and deep research workflows. With AnySearch, we’re focusing on being a broader retrieval layer for agents: web search, vertical sources, URL extraction, and agent-native integrations like APIs, MCP, and Skills, with source attribution and metadata that agents can carry through their workflow.
So if your use case is pure web research, I’d honestly benchmark both. If you want one pluggable search layer that fits into different agent workflows and source types, that’s where we think AnySearch becomes useful.
@conduit_design Heya, great question.
I’d frame the difference more around use case than “better or worse.” AnySearch is built as an agent-native search infrastructure layer that developers can plug into their own agents and products.
AnySearch can be called directly through MCP, Skill, and API, returns structured results, and routes across both general web and vertical sources like finance, academic, legal, business, code, health, patents, and more.
We also put a lot of emphasis on developer control, including source constraints, domain-level policies, provenance, and privacy-friendly usage.
The best way to compare is to try both with your own agent workflow and queries. We’d love for you to test AnySearch directly and see where it fits better for your use case.
@luki_notlowkey Thanks! Yep, that’s exactly the kind of downstream agent use case we care about.
AnySearch returns structured results with source attribution, so agents can cite where a claim came from instead of treating search as a black box. Results are also relevance-ranked, and we expose confidence/freshness-style signals where available so developers can decide how much weight to give each source.
We try to be careful with this though: confidence shouldn’t mean “the AI is definitely right.” It’s a signal for the agent to combine with its own policies, cross-checking, or human review when the stakes are higher.