
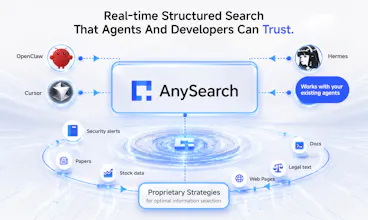
A search tool for agents, not a search box. AI agents are only as good as the information they receive. When connected to AnySearch, your agent gets filtered, de-duplicated, and structured information from trusted sources searched in parallel, helping it produce more reliable results. Free to start.


Launch Team

CloudflareStill paying to deploy your apps? Try Cloudflare Workers for free
Promoted


searching multiple trusted sources in parallel and then deduping sounds great for accuracy but what does that do to latency and cost per query compared to a single search call. for an agent making dozens of tool calls in a session those add up fast, curious if there's a way to tune how many sources it hits per query or if that's fixed
@galdayan Great question — that tradeoff is very real.
Multi-source retrieval can increase cost versus a single-source call, but latency does not have to scale linearly because sources can be queried in parallel and the router does not need to hit every source for every query.
The key is source breadth control. For latency-sensitive agent steps, you want fewer sources and faster returns. For high-stakes or evidence-heavy steps, you may want broader retrieval plus dedupe and reranking.
Our direction with AnySearch is to make this query-aware rather than fixed: route based on domain, freshness needs, source type, and confidence requirements, while letting developers constrain scope with things like domain filters, source types, result limits, or lighter vs deeper retrieval modes.
The goal is not “always search everything,” but to let agents choose the right cost / latency / accuracy tradeoff per query, especially when a session may involve dozens of tool calls.
Congrats for launching! This looks interesting, but since the normal search results are full of ads and SEO content. How do you decide the sources are trusted without filtering out useful information ?
@reda_roqai_chaoui That’s exactly the balance we care about.
We don’t treat trust as a hard whitelist where everything else gets removed. Instead, we look at signals like source type, originality, freshness, relevance, duplication patterns, and whether other credible sources support or contradict it.
The goal is to reduce obvious noise like ads, SEO copies, and low-value duplicates, while still keeping useful edge-case information visible with context. So instead of “trusted or deleted,” it’s more like “useful evidence, with the right confidence and attribution.”
Interesting approach. Structured search that agents can actually work with is a real gap right now. Most search APIs return messy results that need a ton of post-processing before an agent can use them.
How are you handling schema consistency across different data sources? That's been one of the hardest parts in our experience.
@masato_furuno1 Data from different sources perform variations in format. By transforming them into structured contents that can be used by Agents, and by sinking the tasks of cleaning, and filtering to the infra layer, we make the data Agents receive is clean, referenced, and directly inferable.
@terence_lou Makes sense. Having each agent deal with messy data on its own is a pain, so sinking that to infra is smart. What happens when two sources define the same entity differently though? Like conflicting schemas for the same thing.
@terence_lou @masato_furuno1 Yeah, that’s exactly where we try not to be too clever.
When two sources describe the same entity differently, we don’t want to blindly squash them into one “clean” object and lose the disagreement. We normalize the common fields so agents can work with the result, but keep source-specific fields and provenance attached.
So if source A and source B disagree on an attribute, the agent should be able to see that as a conflict, not as a mysteriously averaged answer. In those cases, the useful output is often: “these are probably the same entity, here are the conflicting fields, here is where each version came from.”
Basically, normalize the shape, not the truth.
@terence_lou @ye_y "Normalize the shape, not the truth" - that's a really clean way to put it. Keeping the conflict visible instead of hiding it behind a merged object makes a lot more sense for agents that need to make judgment calls downstream. Nice design choice.
As more AI agents rely on AnySearch, how do you prevent misinformation from propagating through automated workflows?
@robert_dimla Preventing misinformation from propagating through AI workflows is exactly what we want to do and have been solving. We use exclusive algorithms and self built data sources on the search layer to filter out incorrect and outdated information, and improve the ranking of real-time and accurate information sources. We are calling on and inviting more AI developers, companies, or open source projects to use AnySearch for a better search experience and promote the development of the AI industry together.
It seems especially useful for fast-changing coding docs.
@lesley_liu2 Try it, I look forward to your feedback.
@lesley_liu2 Fast-changing docs are a great use case. AnySearch helps agents get real-time, accurate info instead of relying on outdated context. Hope you give it a try :)
@lesley_liu2 Absolutely. Coding docs are one of the clearest use cases.
A lot of agent mistakes come from stale examples, old APIs, or random blog posts outranking the current docs. If the agent can pull fresher, source-attributed docs and examples before acting, it has a much better chance of writing code that actually works.
This feels like it came from actually using agents, not just chasing AI hype.
@eexlkuang_se yes,make agents open their eyes
@eexlkuang_se Bingo. We built AnySearch with real agent workflows in mind, not just AI hype. The goal is to make search work the way agents actually need it to — more reliable info, cleaner context, and results that are easier to use in the workflow.
@eexlkuang_se We’ve built and used agents ourselves, and AnySearch came directly from that experience.
Once agents move beyond demos and start doing real work, search becomes one of the biggest bottlenecks: stale information, noisy results, weak attribution, and messy context. We felt that pain first-hand, so we started building AnySearch as the retrieval layer we wished our own agents had.
The part that stands out is filtering duplicate results and SEO content first.
@nicole_h94 definitely
@nicole_h94 Yep! AnySearch uses its retrieval and ranking pipeline to filter out low-quality, duplicate, and SEO-heavy content.