
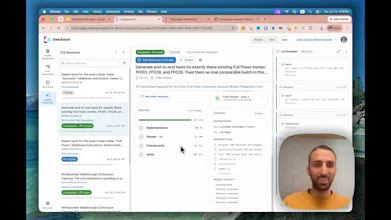
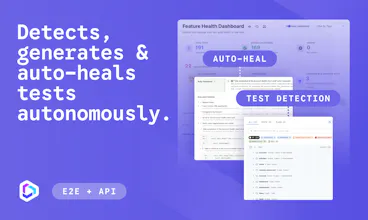
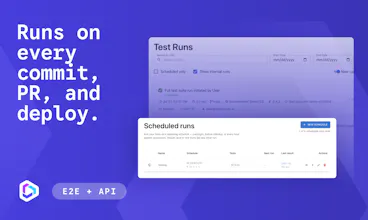
Checksum is an AI-native continuous testing platform for engineering teams shipping faster than manual QA can keep up. It generates, runs, and auto-heals end-to-end and API tests on every pull request, all as standard Playwright code in your own repo. When a test fails, Checksum tells you whether it found a real bug or a stale test, then fixes the false failures so your suite keeps pace with your coding agents.

Free Options
Launch Team / Built With


Viktor.comAn AI coworker that actually does the work
Promoted
👋 Hey Product Hunt, I'm Gal, founder and CEO of Checksum.
A few years ago at my last startup, I watched our team lose entire sprints to test maintenance. Every time the product changed, someone had to go update selectors, re-triage failures, and figure out which broken tests were real bugs and which were just noise. I'd spent years before that building ML models to detect suspicious activity from satellite data—pattern recognition at scale—and it nagged me that software testing was the same kind of problem.
AI coding tools solved generation and teams can now ship far more code than ever. But they didn't solve verification; every PR still needs to be tested and trusted before it ships. Counterpart, an agentic insurance platform, runs a 10x QA team on Checksum at less than half the cost of one offshore developer, and hasn't had a production outage since. Their engineering manager Ron Alexssen put it this way: "For less than half the salary cost of an offshore developer, I have the impact of a full QA team."
That’s why we built Checksum. Our agentic loop runs in two parts:
🔁 Generate and maintain. On every pull request, an agent spins up in a sandbox, detects what changed, and generates or updates your End-to-end and API tests automatically. No written selectors by hand.
🔁 Run, report, fix. Trigger your suite from a PR, the API, or MCP. When something fails, a second agent triages it: real bug, or broken test by a product change? Real bugs route to Jira, Linear, or Slack. Broken tests get fixed autonomously. Söderberg & Partners went from zero to full coverage in weeks and now reclaims 90 hours of manual testing a month. Postilize cut bugs by 70% and sped up engineering cycles by 30%, with zero flaky tests.
Everything ships as standard Playwright code committed to your own repo. No proprietary format, no lock-in. And the agent doesn't just chase easy passing tests, it goes after the hard cases too: auth boundaries, edge flows, the stuff that's tedious to test manually and easy for AI to skip if you let it.
🎁 Product Hunt community gets a free 30-day trial with code PHLAUNCH
We're here all day, ask us anything. 🙏
Would you suggest using this for more elaborate claude code projects (full stack, hosted)? I'm the owner of a few of our internal tools and I'm trying to figure out where I can/should fit something like Checksum into the stack. I'm frequently worried about random bugs and keeping the tools running as smoothly as possible.
@michaelsand Yep, our bread and butter is complex applications
@michaelsand To add a bit more since this sounds like a specific situation: internal tools are a great fit for this, precisely because they're the tools least likely to have dedicated QA watching them. Checksum tests against your actual hosted environment, so it's not limited to a specific stack, and once tests exist they don't just run once, failures get triaged (real bug vs. something that broke because the UI changed) and broken tests get healed rather than left red and forgotten, which is usually where internal-tool test suites quietly die.
Would depend a bit on where your repo and CI live and how your environments are reached, happy to get into specifics if useful. Is the "random bugs" worry mostly about regressions from AI-generated changes specifically, or more general "nobody's watching these tools" risk?
@michaelsand yea full stack (we love playwright + api) and hosted is what we test most often, vpns or proxies very normal for us to need to get set up with clients for internal tool testing. Yea everyone is in nail-biter mode right now with releases. Software Engineering best practices are yet to crystalize for the new normal. We think we've a shot at being one of those must buys
How do teams build confidence in auto healed tests without manually reviewing every change?
@hamza_afzal_butt It's such a great question! You start by reviewing a few changes, and as you see the model making the right decisions, you start to build confidence.
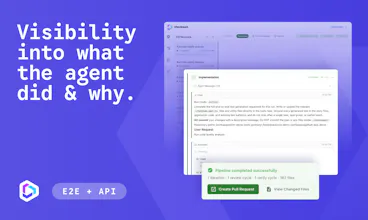
@hamza_afzal_butt Adding a bit more to this, every healed test change lands as an actual diff you can review, not a silent overwrite. So you're never blindly trusting the model, you're reviewing it the same way you'd review any other code change. In practice, teams tend to check closely at first, and once you've seen the same failure mode (a selector rename, say) get correctly resolved a handful of times, you naturally stop needing to check every instance of that type.
Curious what's behind the question for you?
As a marketer, I'm just here to say that I love your tagline ☺️ it makes a pretty intimidating category feel approachable. Congrats on the launch!
@ryanwrites Thank you, that means a lot coming from another marketer! We wanted to convey that this is a solvable problem, and you've got real backup, not another intimidating tool to manage on your own. Really glad it's landing that way. 🙌
@michelle_dailey You nailed it. Well done!!
I work at checksum so grain of salt, but my take:
What surprised me: I came in assuming the hard problem was generating tests. It isn't — models will write plausible-looking tests all day. The hard problem is that "plausible" and "green" are both terrible proxies for "actually proves the feature works." A big part of my job turned out to be making the system distrust its own passing tests.
The moment that sold me: a test broke after a routine frontend change, and the obvious move — the one every human on every team makes ten times a week — was to update the assertion to match the new behavior and get back to green. The agent refused. It walked the diff, decided the new behavior wasn't an intentional change but a regression, and filed it as a product bug instead of "fixing" the test. It was right. A human reviewer would have rubber-stamped the assertion update, the suite would have gone green, and the bug would have shipped with a passing test standing guard over it.
Why verification is the unglamorous problem: when it works, nothing visible happens. There's no demo moment for "this green check is real." So everyone builds the flashy generation demo and quietly ships suites that decay into checkmarks nobody trusts. But an untrusted suite is worse than no suite — you keep paying the maintenance cost and get none of the confidence. Solving that is the actual product, and it's the part nobody wants to put on stage.
@daniel_harkin Thanks for sharing!
@odeth_negapatan1 Good question! We've seen teams measure a few different things depending on their priorities. First, cost per outcome: automated triage runs at roughly $10 per failing test resolved vs. around $78 for fully manual handling. Next is time reclaimed: Söderberg & Partners get back about 90 hours of manual testing a month once their suite was fully automated. And finally speed: Postilize saw engineering cycles get 30% faster alongside a 70% drop in bugs, since less time goes to figuring out whether a red test is a real problem or noise.
I'd say that most teams end up tracking a mix of "hours not spent on maintenance" and "time-to-ship," since the ROI shows up in both places at once, not just one.
@odeth_negapatan1 And thank you for the congrats and questions!
This is one of those problems that becomes more important as AI-assisted development becomes the norm. More generated code means more surface area to validate. Excited to see how Checksum AI evolves!
@tanjum Thanks, Tanjum! That's a clean way of putting it, more generated code really does mean more surface area to validate. Congrats on Wion, going to check it out.