Curious how other early-stage founders and product people manage this.
If you have more than 100 customers, feedback starts to be in 5+ tools, and the synthesis process becomes opening 30 tabs, hoping nothing important is skipped for the questions:
I built idemkit after cleaning up duplicate charges one too many times.
The version everyone writes checks whether a key has been seen and replays the stored response. Two requests a millisecond apart both find nothing and both charge the card. And if the worker dies between charging and recording it, the retry charges again. Neither reproduces locally.
idemkit does it properly: an atomic claim instead of check-then-act, a lease that expires on the storage server's clock, and a fencing token so a stalled worker can't overwrite a good result.
I am so happy to join the fam here, and even happier to have a chance to launch AssetLoom on PH (https://www.producthunt.com/prod...) (thank you PH, this is really awesome).
I keep a daily probe that asks the assistants the buying questions in my category and records every source behind every answer. Last week I pointed it at Google's two AI surfaces, the AI Overview box and the fuller AI Mode, and counted.
Thirteen answers. 168 citations. Every single answer used a different domain for each of its sources. Not one domain was cited twice, in any answer, the whole week. Thirteen of thirteen, no repeats.
That stopped me, because it is the opposite of how a normal search results page behaves. On the ten blue links, one strong site often takes three or four of the top spots. A page that ranks well ranks well repeatedly. Here, ranking well once seemed to use up the domain for that answer.
Why an AI answer looks like this An assistant does not hand you a ranked list. It breaks your question into several smaller ones, runs those, and assembles an answer from the best source it found for each. Google's own patent on query variants (US11663201B2) describes dynamic control that "can often lead to a relatively large (e.g., more than 5, more than 10, or more than 15) quantity of variants."
Over the past several months, I've been building ToolsRoot, a platform with 70+ browser-based tools for PDFs, images, documents, audio, video, and archives.
The biggest surprise wasn't the engineering it was discovering how many everyday file workflows are still surprisingly frustrating.
People often have to:
Visit multiple websites for different file types.
Wait for uploads before anything happens.
Create accounts just to complete a simple task.
Worry about where their files are stored afterward.
I wear an Oura ring and lift 2x a week. Every morning I'd see a readiness score 58, 91, whatever and have no idea what to do with it. Oura tells you how recovered you are. It doesn't tell you how heavy to lift.
So I built ReadyLift. It reads your recovery data (Oura, Whoop, Apple Watch, Garmin) and prescribes the actual weight, sets and reps for today, adjusted against your recent training. Readiness 75 bench 185 instead of 225, and it shows you the math.
The engine is deterministic, not an LLM I wanted the load calculations explainable rather than plausible-sounding. Also works with no wearable at all; manual logging is free.
Solo built . Live on iOS and Android, launching on PH next week.
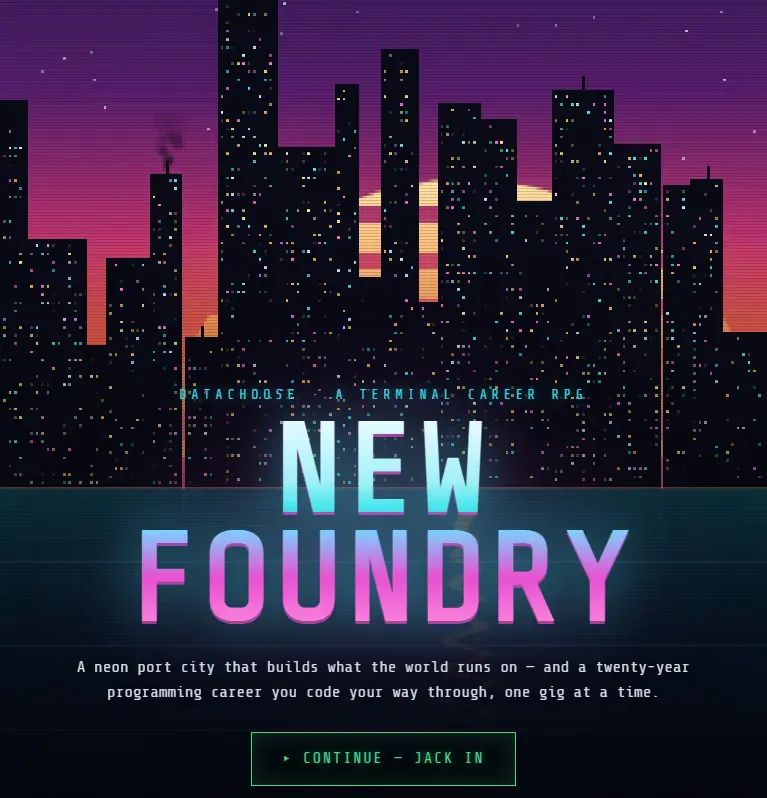
TL;DR: I'm building a cyberpunk terminal RPG that teaches embedded C, Python, and microcontrollers by making you survive as a broke engineer in a rain-soaked 2007 port city. You write real code that runs in the browser. Looking for honest feedback.
We ve been building Cheetu AI an AI tool designed to help people turn meetings, lectures, YouTube videos, and recordings into organized, searchable knowledge, and build your own personal audio knowledge base.